
LitServer
Use LitServer to handle the infrastructure side of serving models: scaling requests, batching inputs, streaming responses, and managing GPU resources. Once the model logic is set up with LitAPI, LitServer optimizes the serving process automatically. It's designed for simplicity, enabling beginners to deploy models efficiently while offering advanced controls for experts to fine-tune performance.
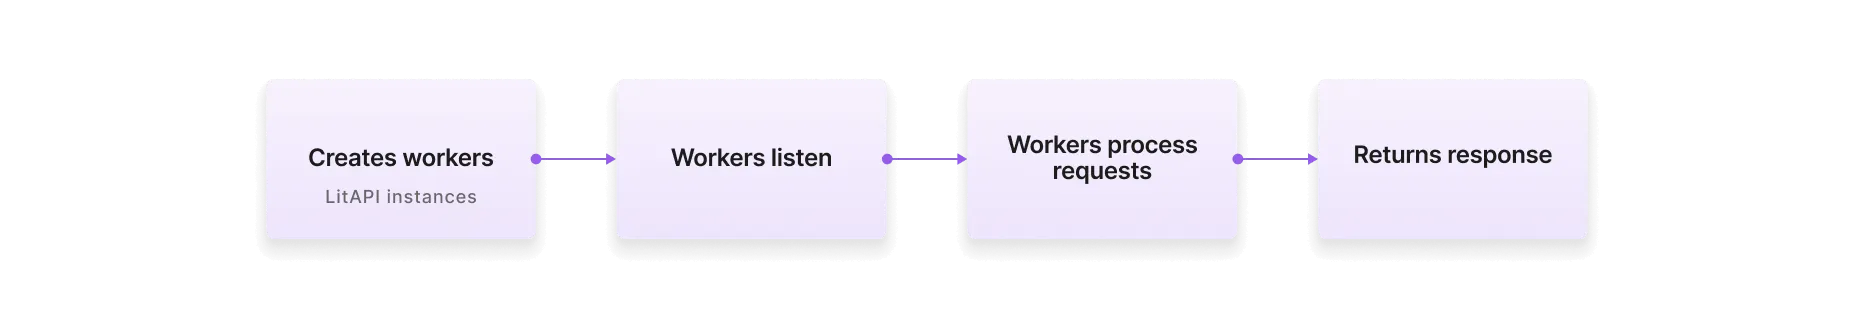
Example:
import litserve in ls

# your defined API (see the LitAPI docs)
api = ls.examples.SimpleLitAPI()

# start the server
server = ls.LitServer(api)
server.run(port=8000)
Parameters
These are all the available LitServer parameters and the default values.
from litserve import LitServer

LitServer(
    lit_api: LitAPI,
    accelerator: str = "auto",
    devices: Union[str, int] = "auto",
    workers_per_device: int = 1,
    timeout: Union[float, bool] = 30,
    max_batch_size: int = 1,  # deprecated and moved to LitAPI
    batch_timeout: float = 0.0,  # deprecated and moved to LitAPI
    stream: bool = False,  # deprecated and moved to LitAPI
    spec: Optional[LitSpec] = None,  # deprecated and moved to LitAPI
)
lit_api
The LitAPI class that defines the API endpoint. The server will manage the API in this argument.
from litserve import LitServer

LitServer(lit_api=...)
import litserve in ls
class SimpleLitAPI(ls.LitAPI):
def setup(self, device):
self.model = lambda x: x**2
def decode_request(self, request):
return request["input"]
def predict(self, x):
return self.model(x)
def encode_response(self, output):
return {"output": output}
api = ls.SimpleLitAPI(litapi=api)accelerator
The type of hardware to use (cpu, GPUs, mps).
from litserve import LitServer

# auto detects the hardware (NVIDIA GPU or Apple (mps) if available)(DEFAULT)
LitServer(accelerator='auto')

# uses CPUs only
LitServer(accelerator='cpu')

# uses any available GPUs
LitServer(accelerator='cuda')

# uses any available Apple GPUs (mps) chips
LitServer(accelerator='mps')
import litserve as ls
api = ls.examples.SimpleLitAPI()
server = ls.LitServer(api, accelerator='cpu')
server.run(port=8000)devices
The number of (CPUs, GPUs) to use for the server.
from litserve import LitServer

# auto detects the number of available devices
LitServer(devices='auto')

# uses 2 CPUs
LitServer(accelerator='cpu', devices=2)

# uses 1 GPU
LitServer(accelerator='cuda', devices=1)

# uses 8 GPUs
LitServer(accelerator='cuda', devices=8)
import litserve as ls
api = ls.examples.SimpleLitAPI()
server = ls.LitServer(api, accelerator='cuda', devices=4)
server.run(port=8000)workers_per_device
Number of workers (processes) per device. For example, if there is 1 GPU with 2 workers, there will be 2 server replicas on that GPU.
from litserve import LitServer

# default (1 worker per device)
LitServer(workers_per_device=1)

# uses 2 workers per device
LitServer(workers_per_device=2)
Example: This example deploys 8 workers per GPU. This is equivalent to 8x4=32 server replicas running on the same 8 GPU machine (yes... 32 server replicas on a single machine).
import litserve as ls

api = ls.examples.SimpleLitAPI()
server = ls.LitServer(api, accelerator='cuda', devices=4, workers_per_device=8)
server.run(port=8000)
timeout
Specifies the maximum time a request can wait in the queue before timing out. If the request is not dequeued and processed within this period, it will return a timeout response. This setting acts as a failsafe to prevent requests from being stuck in the queue indefinitely. However, once a request starts processing, it will run to completion regardless of this timeout.
from litserve import LitServer

# time out after 30 seconds of no response (default)
server = LitServer(timeout=30)
Example: This example times out a request if not response is returned within 10 seconds.
import litserve as ls

api = ls.examples.SimpleLitAPI()
server = ls.LitServer(api, timeout=10)
server.run(port=8000)
healthcheck_path
The URL path for the health check endpoint.
from litserve import LitServer

# the health check API is served from /health (default)
server = LitServer(healthcheck_path='/health')

# name the API to something different ('/status')
server = LitServer(healthcheck_path='/status')
Example: This example creates a health check API under a path called /health/status.
import litserve as ls

api = ls.test_examples.SimpleLitAPI()
server = ls.LitServer(api, healthcheck_path='/health/status')
server.run(port=8000)
max_payload_size
Rejects requests with a payload that is larger than max_payload_size
from litserve import LitServer

# API will not check the payload size (default)
server = LitServer(max_payload_size=None)

# API rejects requests larger than 4096 bytes
server = LitServer(max_payload_size=4096)
Example: This example rejects requests with payload size larger than 4096 bytes.
import litserve as ls

api = ls.test_examples.SimpleLitAPI()
server = ls.LitServer(api, max_payload_size=4096)
server.run(port=8000)
callbacks
The callbacks parameter enables to run custom actions at specific points in the server's lifecycle, such as before or after predictions.
# Logs the prediction time of the model

class PredictionTimeLogger(ls.Callback):
    def on_before_predict(self, lit_api):
        t0 = time.perf_counter()
        self._start_time = t0

    def on_after_predict(self, lit_api):
        t1 = time.perf_counter()
        elapsed = t1 - self._start_time
        print(f"Prediction took {elapsed:.2f} seconds", flush=True)
Example: This is a minimal example that logs the time taken for each prediction.
import time
import litserve as ls

class PredictionTimeLogger(ls.Callback):
    def on_before_predict(self, lit_api):
        t0 = time.perf_counter()
        self._start_time = t0

    def on_after_predict(self, lit_api):
        t1 = time.perf_counter()
        elapsed = t1 - self._start_time
        print(f"Prediction took {elapsed:.2f} seconds", flush=True)

if __name__ == '__main__':
    lit_api = ls.test_examples.SimpleLitAPI()
    server = ls.LitServer(lit_api, callbacks=[PredictionTimeLogger()])
    server.run()
middlewares
Add custom functionality to process requests and responses, such as authentication, logging, or transforming data, before or after they reach the API.
from starlette.middleware.cors import CORSMiddleware
import litserve as ls

# Define CORS middleware with the appropriate arguments
cors_middleware = (CORSMiddleware, {})
server = ls.LitServer(api, middlewares=[cors_middleware])
Example: This is a minimal example that adds a CORS middleware.
from starlette.middleware.cors import CORSMiddleware
import litserve as ls

if __name__ == "__main__":
    api = ls.test_examples.SimpleLitAPI()
    cors_middleware = (
        CORSMiddleware,
        {
            "allow_origins": ["*"],
            "allow_methods": ["GET", "POST"],
            "allow_headers": ["*"],
        }
    )
    server = ls.LitServer(api, middlewares=[cors_middleware])
    server.run(port=8000)
track_requests
Track the total number of active requests in the queue across API servers by setting track_requests=True in the LitServer class. This can be useful to track as metric for creating the scaling strategy.
import litserve as ls

api = ls.test_examples.SimpleLitAPI()
server = ls.LitServer(api, track_requests=True)
server.run(port=8000)
Example: The following middleware can track and be used to log the total number of requests in the queue.
import litserve as ls

class RequestTracker(ls.Callback):
    def on_request(self, active_requests: int, **kwargs):
        # do something with active_requests
        print(f"Active requests: {active_requests}", flush=True)

class SimpleLitAPI(ls.LitAPI):
    def setup(self, device):
        self.model = lambda x: x ** 2

    def decode_request(self, request):
        return request["input"]

    def predict(self, x):
        return self.model(x)

    def encode_response(self, output):
        return {"output": output}

if __name__ == '__main__':
    api = SimpleLitAPI()
    server = ls.LitServer(api, callbacks=RequestTracker(), track_requests=True)
    server.run()
fast_queue
Replaces the standard Python multiprocessing.Queue with a ZeroMQ-based implementation, offering improved performance in scenarios involving high-throughput or real-time communication—such as streaming responses from language models.
import litserve as ls

api = ls.test_examples.SimpleLitAPI()
server = ls.LitServer(api, fast_queue=True)
server.run(port=8000)
Example: This example demonstrates how to use a ZeroMQ-backed queue in LitServe to enable efficient multiprocessing communication—particularly useful for high-throughput or streaming applications like language model output.
import litserve as ls

class SimpleStreamAPI(ls.LitAPI):
    def setup(self, device) -> None:
        self.model = lambda x: x

    def decode_request(self, request):
        return request["input"]

    def predict(self, x):
        for i in range(1000):
            yield self.model(i)

    def encode_response(self, output):
        for out in output:
            yield {"output": out}

if __name__ == "__main__":
    api = SimpleStreamAPI()
    server = ls.LitServer(api, stream=True, fast_queue=True)
    server.run(port=8000)
Methods
run
Run the LitServe server to handle API requests and distribute them to LitAPI inference workers.
def run(
        self,
        host: str = "0.0.0.0",
        port: Union[str, int] = 8000,
        num_api_servers: Optional[int] = None,
        log_level: str = "info",
        generate_client_file: bool = True,
        api_server_worker_type: Literal["process", "thread"] = "process",
        pretty_logs: bool = False,
        **kwargs,
    )
Parameters
Example: Call .run after initializing the server.
import litserve as ls

api = ls.examples.SimpleLitAPI()
server = ls.LitServer(api)

# Basic
server.run()

# Production
server.run(
    port=8080,
    num_api_servers=4,
    log_level="warning"
)


# Development
server.run(
    log_level="debug",
    pretty_logs=True,
    generate_client_file=True
)
Properties
Was this page helpful?
Thanks for the feedback.