
Streaming
LitServe enables streaming which allows the server to return results incrementally rather than all at once. This allows users to consume the server responses while they are still being delivered. If you've loaded a video incrementally or used a web application like ChatGPT where responses come incrementally, you've seen a streaming server in action.
Background
What is Streaming?
Streaming allows a web server to continuously transmit data from the server to the client. For example, this could be chat messages generated word by word from a model or video frames from a video. This differs from traditional web servers, which have a more discrete communication style, typically providing one response per request.
Applications to LLMs
Large language models (LLMs) generate responses one token (approximately one word) at a time. Streaming allows a continuous response to be sent to the client as the language model generates each token.
An example of streaming chatbot.
Applications to video models
Video models generate and return a few frames at a time. Streaming allows the server to generate long videos sequentially that can be consumed as more frames are generated.
Streaming generates videos frame by frame.
Python generators
Generators are a special type of function in Python that allow you to iterate over a sequence of values without storing the entire sequence in memory. They are useful for efficiently handling large data or streams of data, as they generate items one at a time on-the-fly.
A generator function is defined like a normal function but uses the yield keyword to return values one at a time. Here is a simple example:
def create_n_digits(n):
    for i in range(n):
        yield i

if __name__=="__main__":
    digits = create_n_digits(5)
    print(digits)
    # <generator object create_n_digits at 0x102be7510>

    # `digits` is a generator and need to iterate over it to unpack the content
    for item in digits:
        print(item)
    # 0
    # 1
    # 2
    # 3
    # 4
Enable Streaming
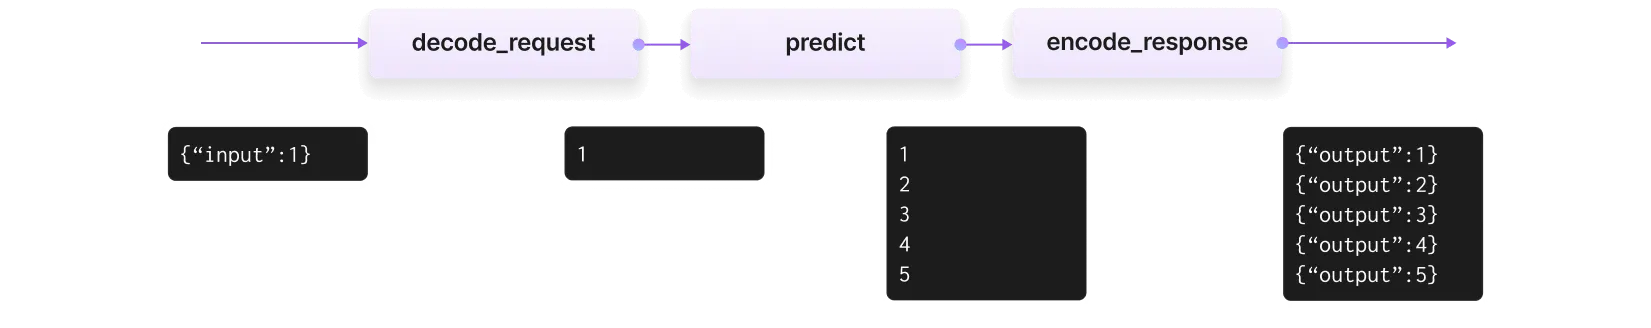
LitServe continuously sends partial responses as they become available.
To enable streaming:
- Set the
streamargument toTruein theLitServerclass. - Yield each prediction one at a time in the
predictmethod, simulating the streaming of data. - Encode each data item produced by the
predictmethod in theencode_responsemethod.
The following diagram demonstrates the flow of data during the streaming of a prediction:
Server
To create a streaming server using LitServe, implement the predict and encode_response methods in the LitAPI class as Python generators. Additionally, set the stream argument to True for the LitServer class. This setup allows the server to send responses incrementally as they become available, which is particularly useful for real-time applications.
Here is a toy example demonstrating a server that streams 10 digits.
import litserve as ls

class SimpleStreamAPI(ls.LitAPI):
    def setup(self, device) -> None:
        self.model = lambda x: x

    def decode_request(self, request):
        return request["input"]

    def predict(self, x):
        for i in range(10):
            yield self.model(i)

    def encode_response(self, output):
        for out in output:
            yield {"output": out}

if __name__ == "__main__":
    api = SimpleStreamAPI(stream=True)
    server = ls.LitServer(api)
    server.run(port=8000)
Client
Make a request to the server and iterate over the streaming content as follows:
import requests

url = "http://127.0.0.1:8000/predict"
resp = requests.post(url, json={"input": 1.0}, headers=None, stream=True)

# Iterate over each line of the streamed response
for line in resp.iter_lines():
    if line:
        print(line.decode("utf-8"))
Examples
Streaming with Llama 3
This example serves a Llama 3 model using LitGPT and streams the generated text.
import litgpt
import litserve as ls

class Llama3API(ls.LitAPI):
    def setup(self, device):
        self.llm = litgpt.LLM.load("checkpoints/meta-llama/Meta-Llama-3-8B-Instruct")

    def decode_request(self, request):
        return request["prompt"]

    def predict(self, prompt):
        yield from self.llm.generate(prompt, max_new_tokens=200, stream=True)

    def encode_response(self, output):
        for out in output:
            yield {"output": out}

if __name__ == "__main__":
    api = Llama3API(stream=True)
    server = ls.LitServer(api)
    server.run(port=8000)
Make an API call to the server by sending a text prompt as follows:
import requests, json

data = {"prompt": "What is the capital of France?"}

response = requests.post(url="http://127.0.0.1:8000/predict", json=data, stream=True)

for line in response.iter_lines(decode_unicode=True):
    if line:
        print(json.loads(line)["output"], end="")
Following video shows streaming text output generated with a Llama 3 model.
Llama 3 streaming example
Was this page helpful?
Thanks for the feedback.