
Batching
Individual inference requests are processed one at a time, limiting system efficiency and underutilizing available hardware resources. This sequential processing reduces throughput, especially under high load, and prevents full use of multi-core CPUs or GPUs. LitServe enables request batching, combining multiple incoming requests into a single batch that can be processed in parallel. It improves system throughput and resource utilization with minimal latency impact, making it more scalable under real-world workloads.
Background
What is Batching?

Batching is the process of grouping multiple individual requests together to process them simultaneously. This technique optimizes computational efficiency, allowing for better utilization of hardware resources such as CPUs and GPUs. Batching can be particularly effective in scenarios where the overhead of processing each request individually is high.
Application of Batching
Batching is essential for high-throughput systems where minimizing latency per request is less critical than maximizing overall throughput.
Sending requests
When dynamic batching is enabled in LitServe, the server automatically groups multiple client requests together to process them in batches. This improves throughput by optimizing resource usage (e.g., CPUs and GPUs) without requiring any special effort from the client.
The following are the key points for clients to consider when sending requests with batching enabled:
- No client changes: Continue sending requests as usual. There is no need to batch the requests on the client side, as the server handles batching behind the scenes.
- Parallel requests: A client can make multiple requests in parallel. The server will group and process them efficiently.
- Response handling: The client will receive individual responses as before, with the server managing the batching process internally.
Enable batching
To enable batching in LitServe, set the max_batch_size argument to match the batch size that your model can handle and implement LitAPI.predict to process batched inputs.
When batching is enabled, the predict method will be called with a group of outputs from decode_request.
Server
The following server configuration attempts to aggregate a maximum batch size of 8 within 50 milliseconds and process them together. You can control the wait time to aggregate requests into a batch with the batch_timeout argument.
LitServe automatically stacks NumPy arrays and PyTorch Tensors along the batch dimension before passing them to the predict method. If not, the predict method receives a list of inputs after processing them with the decode_request method.
import numpy as np
import litserve as ls

class SimpleBatchedAPI(ls.LitAPI):
    def setup(self, device):
        self.model = lambda x: x ** 2

    def decode_request(self, request):
        return np.asarray(request["input"])

    def predict(self, x):
        result = self.model(x)
        return result

    def encode_response(self, output):
        return {"output": output}

if __name__ == "__main__":
    api = SimpleBatchedAPI(max_batch_size=8, batch_timeout=0.05)
    server = ls.LitServer(api)
    server.run(port=8000)
Client
With dynamic batching, the client request format doesn't change. You can make requests to the server with multiple clients in parallel, and the server will batch the requests, process them, and return the response to each client.
import requests

response = requests.post("http://127.0.0.1:8000/predict", json={"input": 4.0})
print(response.json())
When to avoid batching
While batching increases the system throughput, there are some scenarios where it's not recommended to use batching.
Low traffic / infrequent requests: Few users or sporadic request patterns will rarely form batches, making batching ineffective or even slower.
Latency-critical applications: Real-time responsiveness is essential (e.g., online gaming). Even the small wait time to gather a batch (e.g., batch_timeout=0.01) can degrade user experience.
Models or inputs that don’t support batching: Some models are not designed to accept batched input or require complex batching logic.
Resource constraints: Limited CPU/GPU memory where batching might cause OOM errors or degrade performance.
Batching lifecycle
When batching is enabled, the server groups requests up to max_batch_size and sends them together to the predict method.
Simply put, the output of decode_request is grouped up to the batch size. Then that group is sent to the predict method.
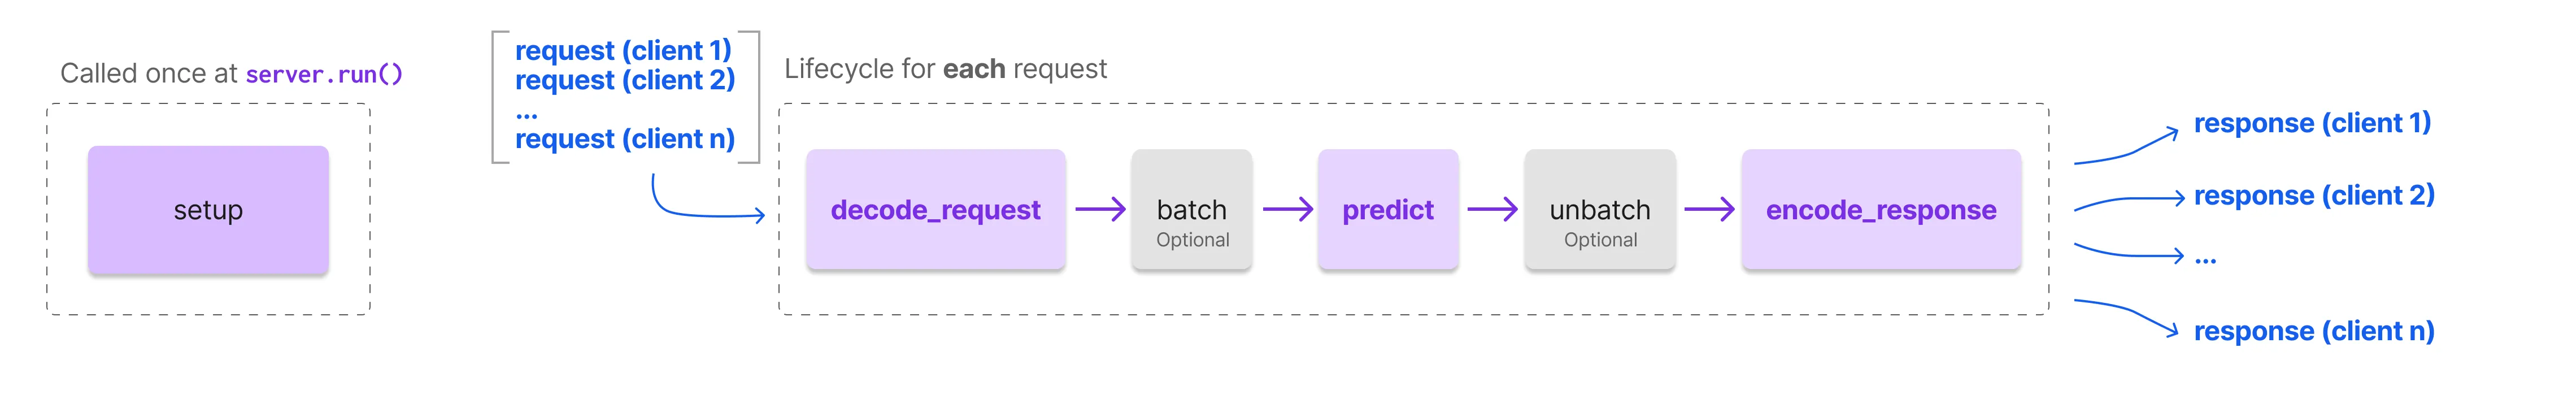
setup is called once at the beginning when the server starts. Use setup to:
- load data
- initialize models
- setup database connections
- load embeddings
- etc...
Once the server has initialized, when batching is enabled, the server groups *n *requests specified in LitServer(max_batch_size=n) into a *batch *and sends the batch all at once through LitAPI in this order:
decode_request: Convert incoming request payloads into model-ready inputs.batch: Optionally define how to group the multiple requests. When not specified, LitServe uses heuristics to automatically do it.predict: Runs inference on the model(s) using the output of decode_request.unbatch: Optionally define how to map a batch to individual responses. When not specified, LitServe uses heuristics to automatically do it.encode_response: Converts the output of predict into a response payload.
Advanced functionality
LitServe automatically stacks NumPy arrays and PyTorch tensors along the batch dimension before calling the LitAPI.predict method and splits the output across requests afterward. You can customize this behavior by overriding the LitAPI.batch and LitAPI.unbatch methods to handle different data types manually.
Override batch and unbatch
To override the default batching behavior, create a subclass of LitAPI and implement the batch and unbatch methods.
In this example, inputs are stacked as a NumPy array to form a batch and unbatch converts the NumPy array back to a Python list.
import numpy as np
import litserve as ls

class CustomBatchedAPI(ls.examples.SimpleBatchedAPI):
    def batch(self, inputs):
        return np.stack(inputs)

    def unbatch(self, output):
        return list(output)

if __name__ == "__main__":
    api = CustomBatchedAPI(max_batch_size=8, batch_timeout=0.05)
    server = ls.LitServer(api)
    server.run(port=8000)
With these customizations, you can handle different data types or processing requirements that may not be supported by the default batching behavior.
Examples
Text classification API
The following example demonstrates serving a text classification model with a maximum batch size of 8 and a batch timeout of 10 ms. The server takes a text input and returns the predicted label as the response.
from transformers import pipeline
import litserve as ls

class TextClassificationAPI(ls.LitAPI):
    def setup(self, device):
        self.model = pipeline("sentiment-analysis", model="stevhliu/my_awesome_model", device=device)

    def decode_request(self, request):
        return request["text"]

    def predict(self, x):
        return self.model(x)

    def encode_response(self, output):
        return output["label"]

if __name__ == "__main__":
    api = TextClassificationAPI(max_batch_size=8, batch_timeout=0.01)
    server = ls.LitServer(api)
    server.run(port=8000)
Use the following client to query the server or open the OpenAPI swagger docs (http://localhost:8000/docs) to query the server.
import requests

url = "http://localhost:8000/predict"
payload = {"text": "I love this product"}
response = requests.post(url, json=payload)
Was this page helpful?
Thanks for the feedback.