
Custom inference engine
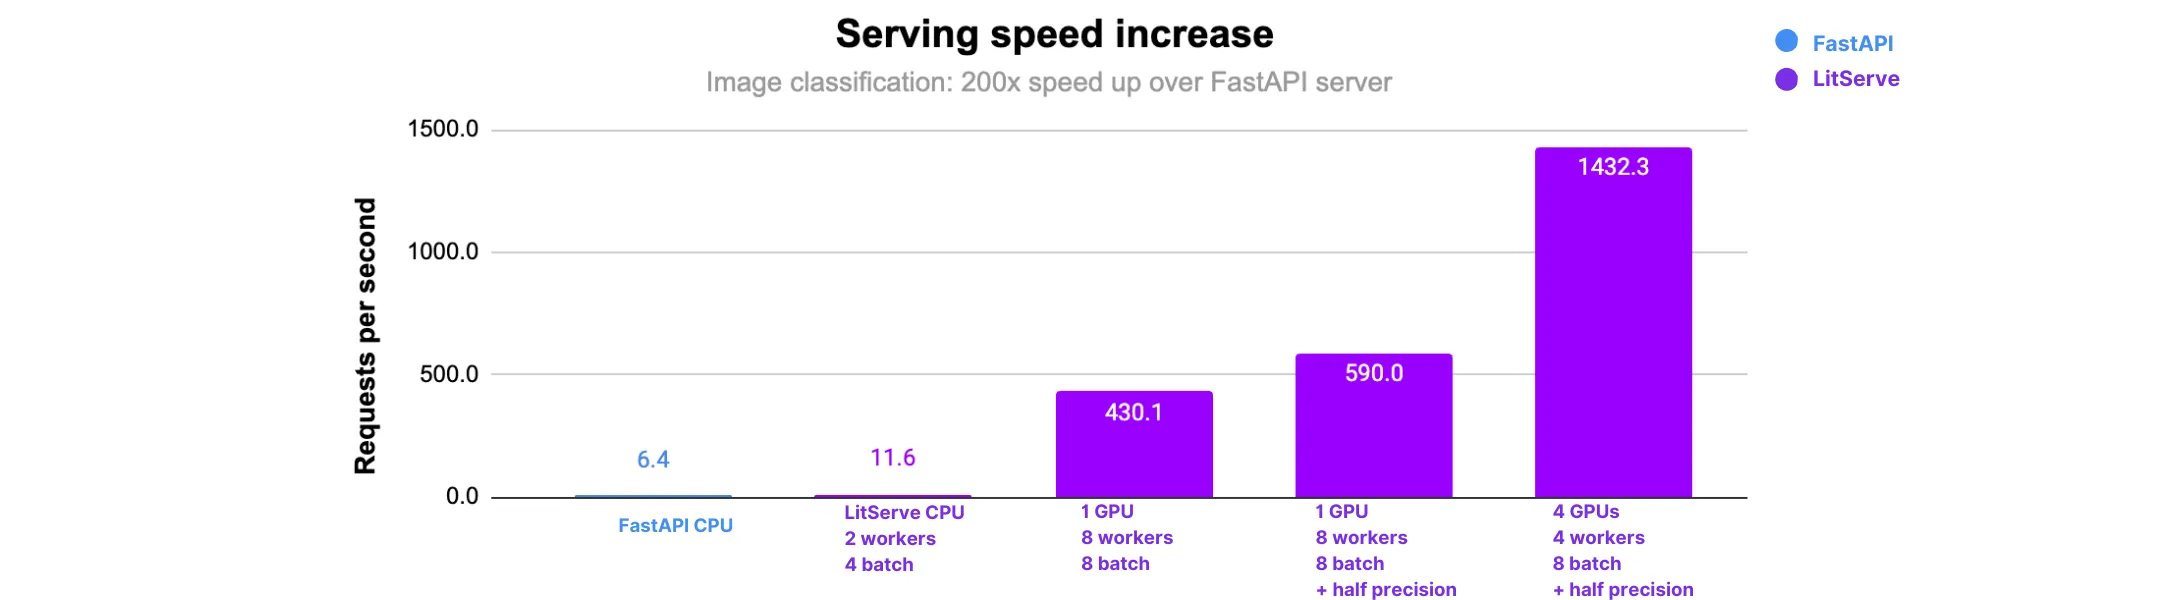
Let's learn the basics with a simple hello world server. The next guide deploys a real server and speeds it up by 200x.
Hello world server
First install LitServe
pip install litserveFull server
Let's deploy an AI "inference" pipeline. This pipeline has multiple "models" to illustrate the flexibility of LitServe to go beyond 1 model. As fancy as they may appear, AI models are ultimately math functions 😉.
Create a server.py file, paste this code in it and run it to deploy your model!
import litserve as ls

class SimpleLitAPI(ls.LitAPI):
    def setup(self, device):
        self.model1 = lambda x: x**2
        self.model2 = lambda x: x**3

    def decode_request(self, request):
        return request["input"]

    def predict(self, x):
        squared = self.model1(x)
        cubed = self.model2(x)
        output = squared + cubed
        return {"output": output}

    def encode_response(self, output):
        return {"output": output}

if __name__ == "__main__":
    api = SimpleLitAPI()
    server = ls.LitServer(api, accelerator="auto")
    server.run(port=8000)
Deploy the server:
lightning api deploy server.py --cloud

lightning api deploy server.py
LitAPI overview
The first step is to implement the LitAPI class which defines the lifecycle of a single request or batch.
import litserve as ls

class SimpleLitAPI(ls.LitAPI):
    def setup(self, device):
        self.model1 = lambda x: x**2
        self.model2 = lambda x: x**3

    def decode_request(self, request):
        return request["input"]

    def predict(self, x):
        squared = self.model1(x)
        cubed = self.model2(x)
        output = squared + cubed
        return {"output": output}

    def encode_response(self, output):
        return {"output": output}

if __name__ == "__main__":
    api = SimpleLitAPI()
    server = ls.LitServer(api, accelerator="auto")
    server.run(port=8000)
Think of this as organizing the key code from a FastAPI server into a clean, readable structure that LitServe can autoscale across workers, GPUs, etc...
LitServer overview
The LitServer (a FastAPI app) is responsible for starting the http server, calling LitAPI at the right time, and autoscaling across GPUs, etc... All special functionality such as streaming, batching, etc... are handled by LitServer.
import litserve as ls

class SimpleLitAPI(ls.LitAPI):
    def setup(self, device):
        self.model1 = lambda x: x**2
        self.model2 = lambda x: x**3

    def decode_request(self, request):
        return request["input"]

    def predict(self, x):
        squared = self.model1(x)
        cubed = self.model2(x)
        output = squared + cubed
        return {"output": output}

    def encode_response(self, output):
        return {"output": output}

if __name__ == "__main__":
    api = SimpleLitAPI()
    server = ls.LitServer(api)
    server.run(port=8000)
Enable optional features to increase performance or customize it to make specialized servers for things like LLMs or vision models.
if __name__ == "__main__":
    api = SimpleLitAPI(
      stream=True,
      max_batch_size=10,
      spec=ls.OpenAISpec()
    )
    server = ls.LitServer(
      api,
      accelerator="auto",
      middlewares=[cors_middleware]
    )
    server.run(port=8000)
Refer to the features section for 20+ more features.
Hosting options
Lightning AI
Deploy servers via Lightning AI for free out-of-the-box features like scale-to-zero, autoscale up on demand, enterprise-grade RBAC, multi-node inference, and more.
To deploy on Lightning AI, simply run LitServe with the lightning CLI. This will automatically package the server into a Docker container (which you can configure), upload to the Lightning container registry, and deploy to a serverless endpoint.
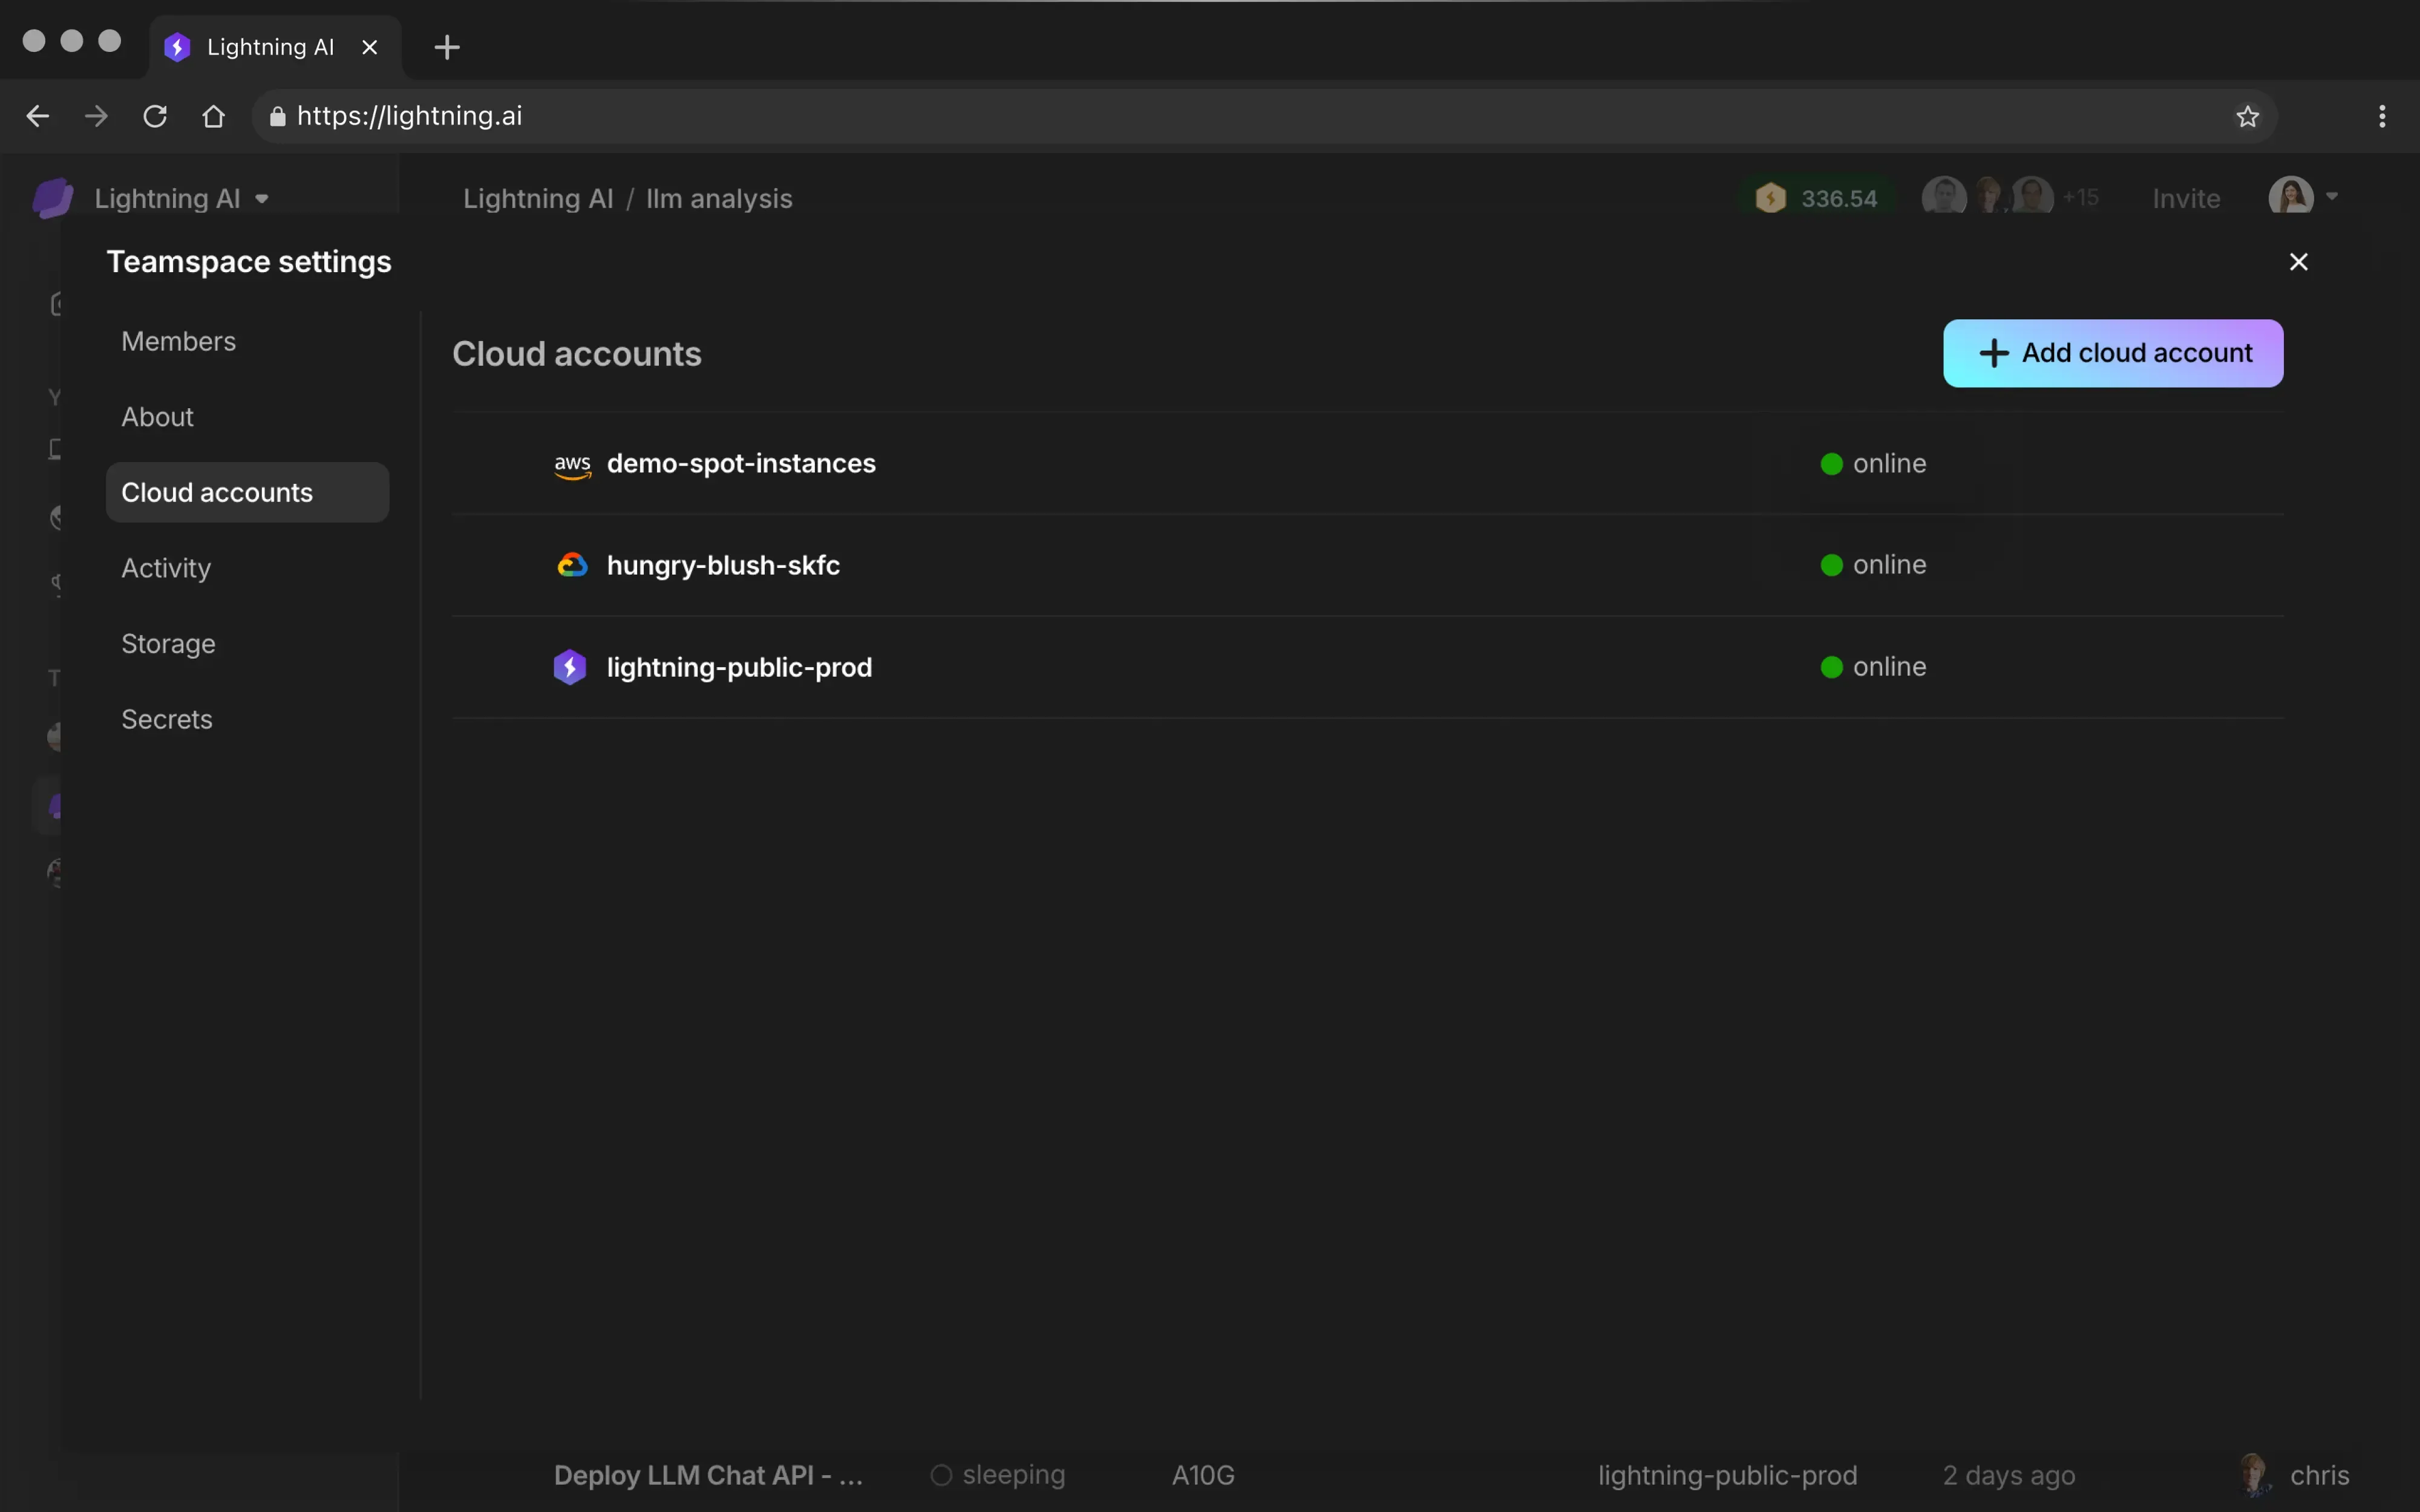
lightning api deploy server.py --cloudConnect your cloud on Lightning AI to deploy via your own private cloud (VPC). This also lets you consume your cloud credits, enterprise-commitments, etc...
Self host
You can also run LitServe anywhere you want and manage the hosting yourself. Simply run in local mode.
lightning api deploy server.pyNext Steps
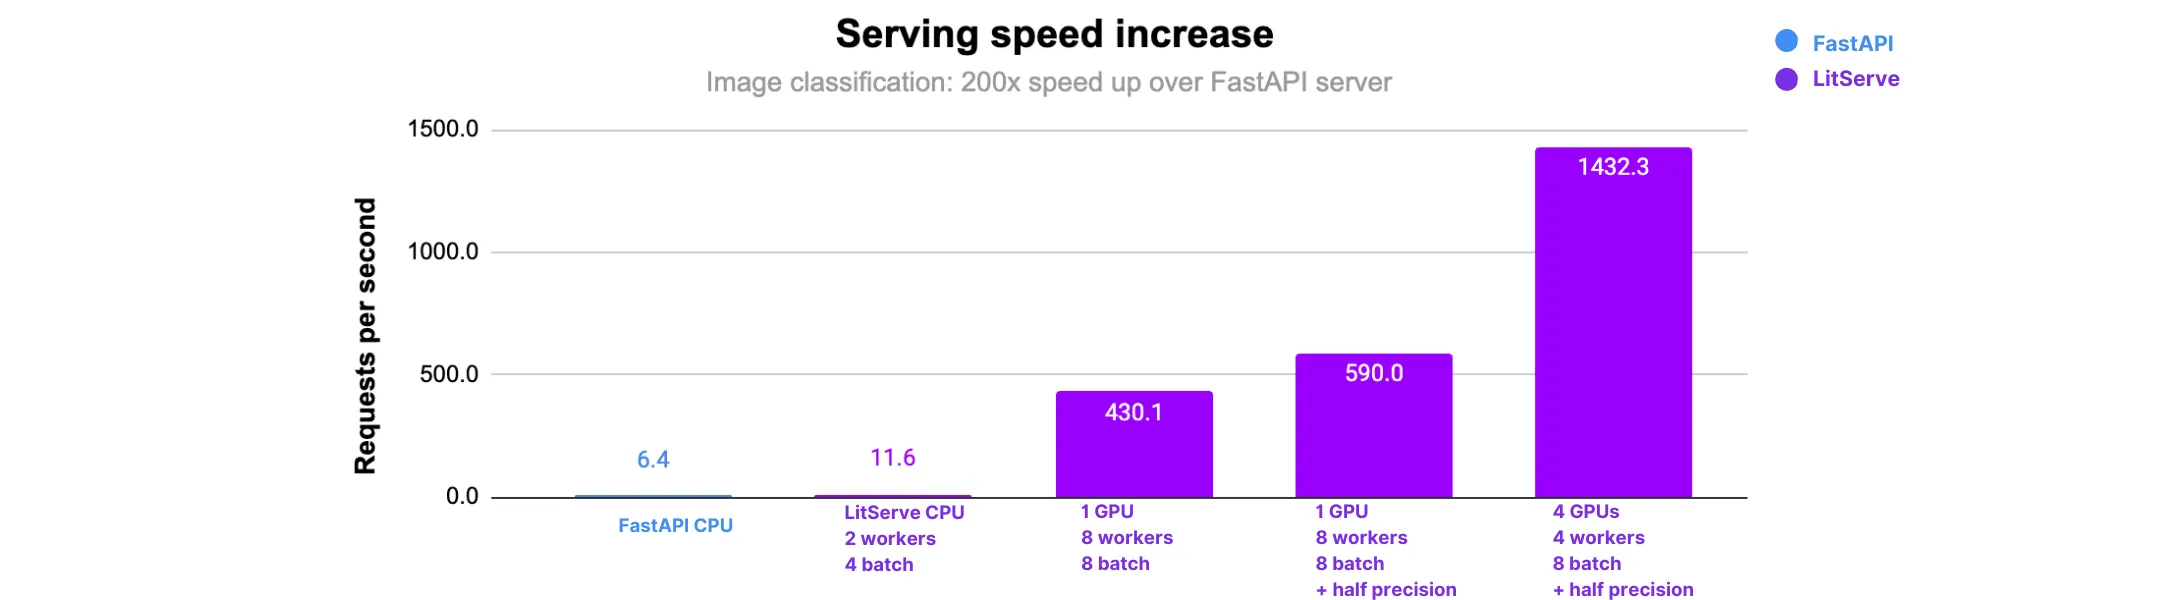
Deploy a realistic example and learn to make it 200 times faster.
Was this page helpful?
Thanks for the feedback.